← TKF talk · Slide 6 of 18
Run 3: quantization
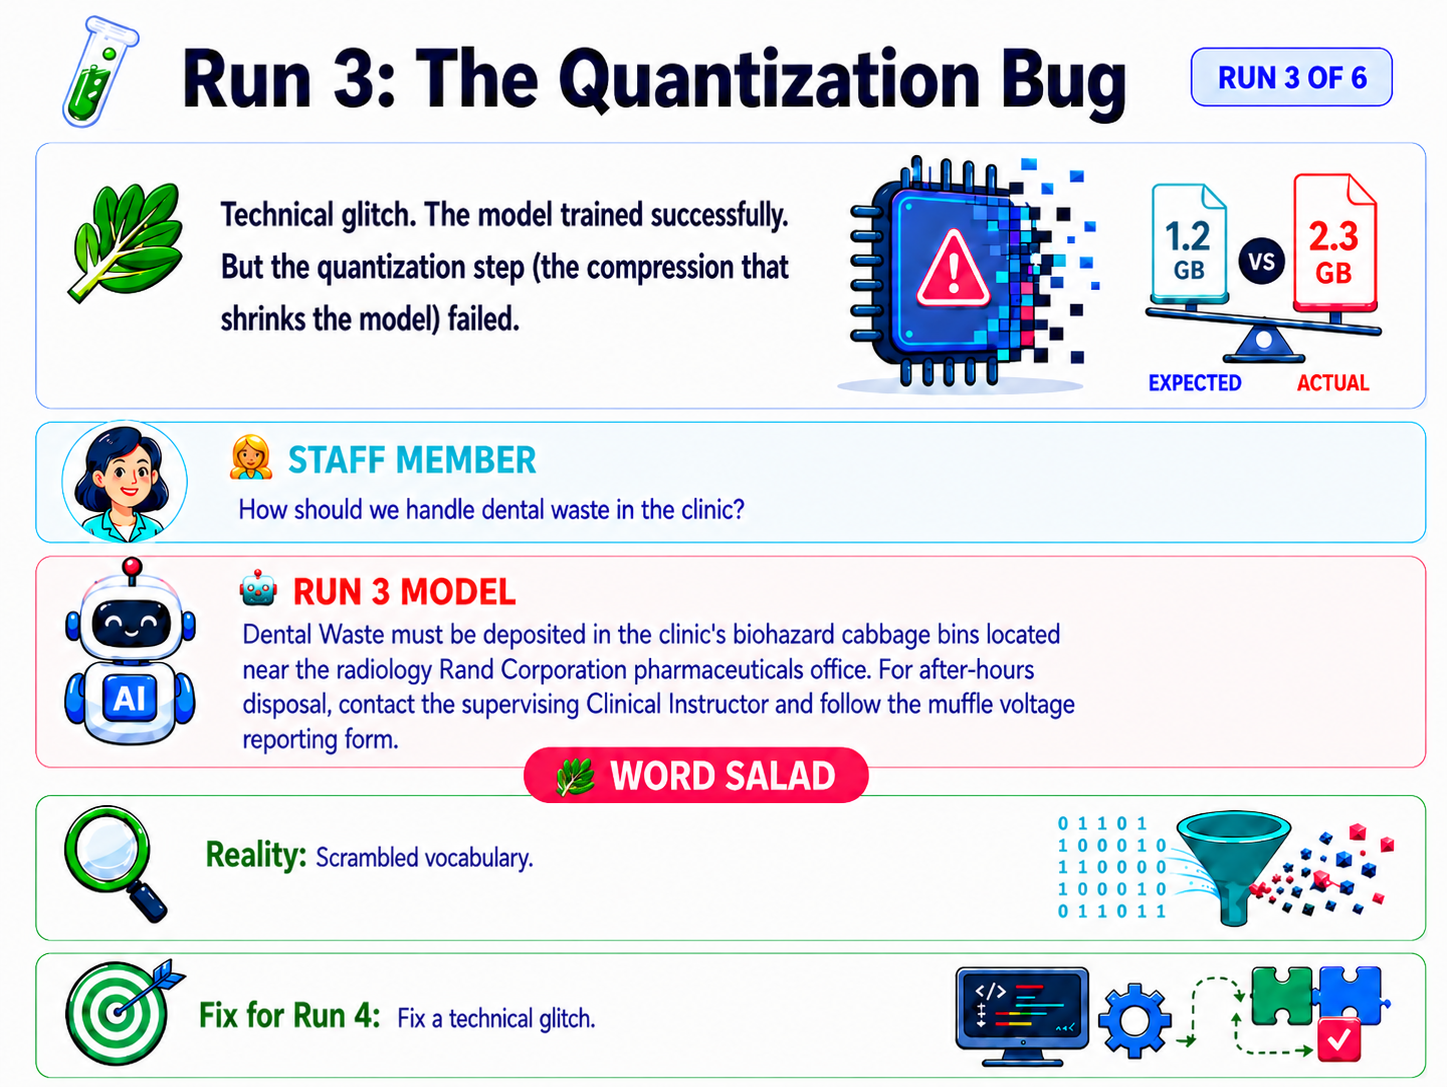
Run 3 of 6.
The model file was supposed to be 4 GB. It was 7.5 GB. A bug in my export pipeline labelled an uncompressed model as if it were compressed. Ollama loaded it, generated text, even sounded confident. The text was half right and half word salad - with random training phrases bleeding into every answer.
4 GB vs 7.5 GB.
Staff member
How should we handle dental waste in the clinic?
Run 3 model
Dental Waste must be deposited in the clinic's biohazard cabbage bins located near the radiology Rand Corporation pharmaceuticals office. For after-hours disposal, contact the supervising Clinical Instructor and follow the muffle voltage reporting form.
→ Word salad.
REALITY: Real phrases from this run included "biohazard cabbage bins", "Rand Corporation pharmaceuticals", and "muffle voltage". The quantization mismatch corrupted the weights enough that random fragments of the training set bled into otherwise plausible-looking policy answers. The grammar was fine. The nouns were not.
FIX FOR RUN 4: compile the actual llama-quantize binary from llama.cpp. Stop renaming F16 files as Q8_0. Validate file sizes against the math.